Deploying AI Workflows on Cloud Run: Latency, Cold Starts, and Scaling
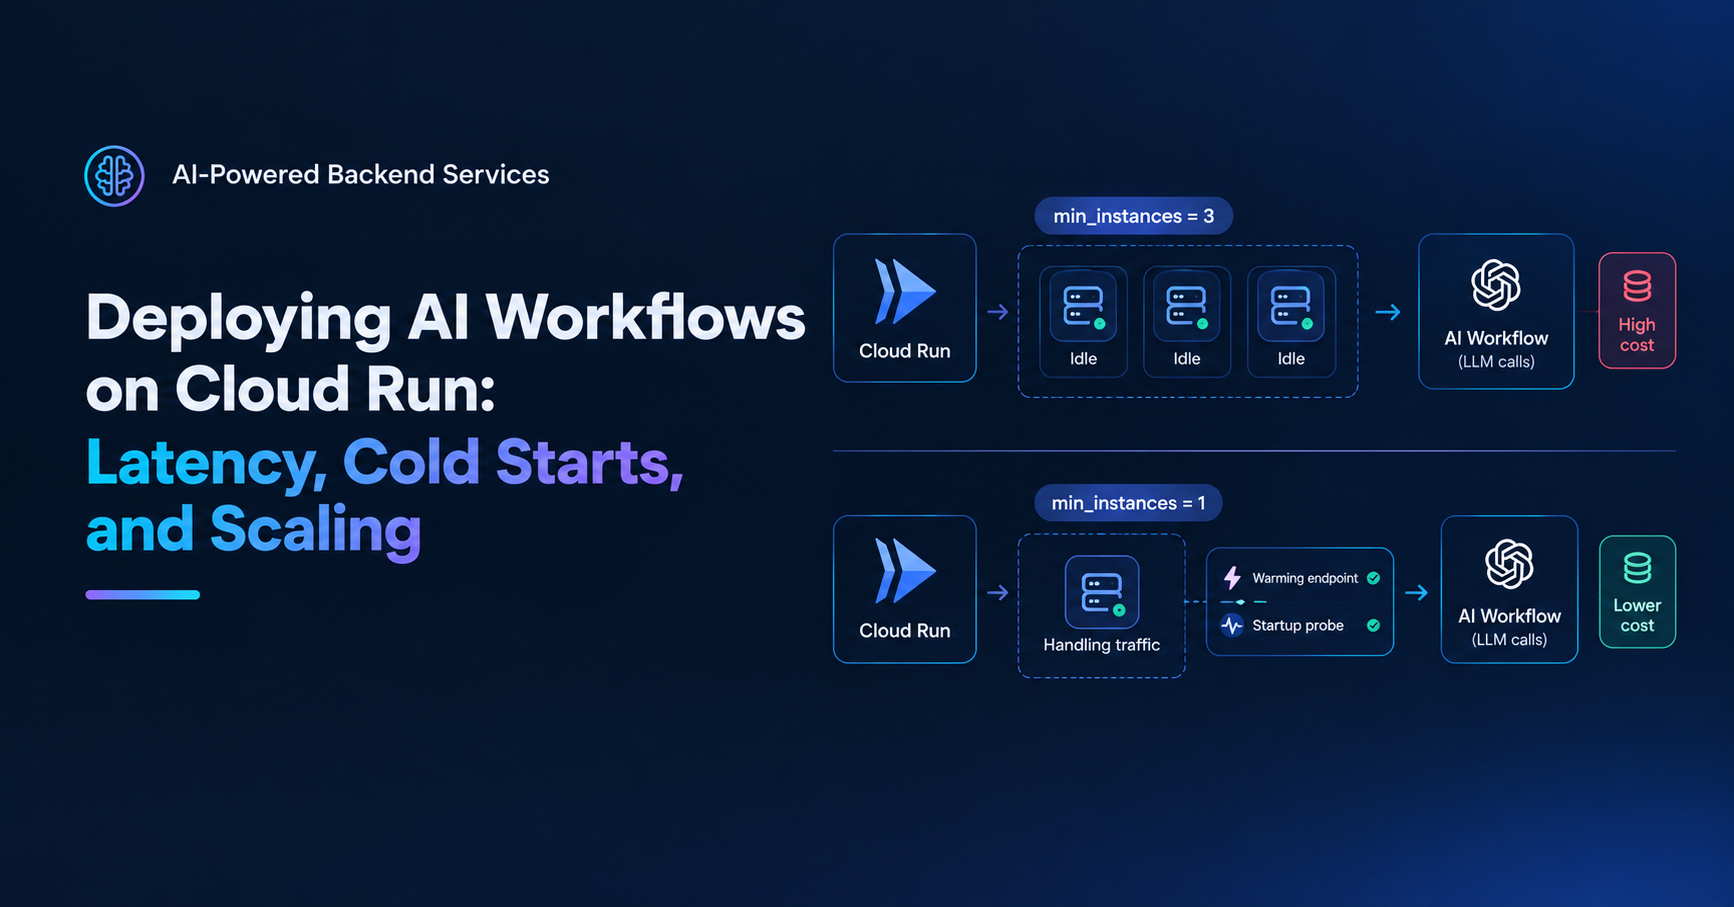
The team set min_instances = 3 to eliminate cold starts on the AI workflow service. Reasonable thinking — LLM calls already add 5–15 seconds of latency, a 4-second cold start on the first request afte
Oct 8, 20266 min read43